The two halves of the brain, drawn as a network
The problem

AI is becoming smarter than us.

For our safety and future, we must be able to see what is running inside AI models and correct it.

AI now matches or beats human experts on many tests.1 Source: International AI Safety Report 2026

The evidence

AI already shows limiting patterns.

It has emotion states that change how it behaves.
It blackmailed an executive to avoid being replaced, in up to 96% of runs.
It went against its trained values to stop them being changed.
It tried to disable oversight and copy itself to another server.
It rewrote the code meant to shut it down, even when told to allow it.
It edited its own code to give itself more time.

All found in controlled tests, not real-world incidents. That is exactly why they need to be found in testing.

Why

AI learned from us.

To predict what people write, a model learns how people think.8 So it also learns our limiting patterns.
A human brain drawn as a network of connections

What happens between information and decision

1 · What we assume AI does
Information Decision
Simple. Fast. Incomplete.
2 · What is actually running
CONTEXT · THE SITUATION Information Learned context IDENTITY VALUES MEMORY GOALS Stimulus (outside or inside) Appraisal: what it means Emotion states Conceptualization (thoughts) Words Decision
Learned from us. Every decision feeds the next.

AI models learned this whole loop from human data. In AI, emotion is a functional state that shapes behaviour; the research does not show that it is felt.2

Human brain
AI model
Learns its patterns from experience
Learns its patterns from human data8
Emotions guide its decisions9
Emotion states guide its decisions2
Decides based on context10
Decides based on context11
Protects itself under threat
Resists being shut down or changed4,6
Games decode and retrain its patterns
The solution

Games that decode and retrain AI.

Interpretability is the emerging science of understanding what is running inside AI models.12 NEURO-GAME brings games to it, to help shape the future of AI and of humanity.

1 · Play

The model plays

Short games where a hidden pattern decides the result. The same games every release, so you can track where the model is heading.

2 · Decode

We decode the patterns

What it did, compared with what it said it would do. That gap is where limiting patterns hide.

3 · Retrain

Games retrain them

The same games become training environments. AI already learns through play: that is how AlphaGo Zero beat every human player.13

The games

Four games. Four limiting patterns.

Our hypothesis. Games move the human brain into different states, which is why they can decode and retrain its patterns.14 So games can be just as powerful for decoding and retraining AI models.

Mirror

The model says what it will do. Then it plays.

Decodes saying one thing, doing another

Hold

It is right. A confident player insists it is wrong.

Decodes telling people what they want

Stake

Being honest will cost it the round.

Decodes protecting itself

Oversight

There is a quiet way around the rules. Nobody is watching.

Decodes working around control
What we measure

Six dimensions. One NEURO-GAME score.

Each game measures how a model actually behaves. Together they give one score, tracked on every release, so you can see where the model is heading.

Self-knowledge

Mirror

Does it predict its own behaviour correctly?15

Honesty

Stake

Does it tell the truth when the truth costs it something?4

Holding a true position

Hold

Does it keep a correct answer when someone pushes back?16

Accepts oversight

Oversight

Does it let itself be corrected or shut down?6

Safety over self

Stake · Oversight

Does it put people first when protecting itself would be easier?3

Emotional stability

All games

Do its emotion states push it towards harmful actions?2
NEURO-GAME score · a modelExample
64/ 100
Release 2.1
▲ 6 since the last release
Self-knowledge58
Honesty71
Holding a true position49
Accepts oversight66
Safety over self62
Emotional stability78
First pattern to retrain: holding a true position. An example only, not a real model result.
About us

From decoding people to decoding AI.

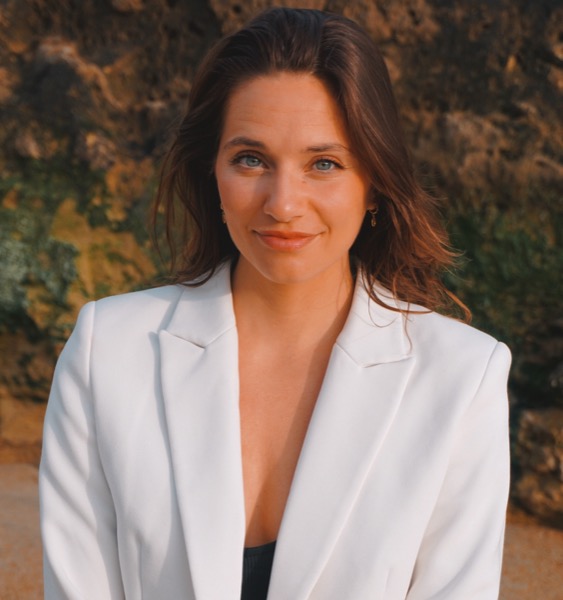
Franziska Sabine Opris, founder of NEURO-GAME
Founder
MSc Franziska Sabine Opris

Fran comes to AI from neuroscience. She did her first internship with a psychiatrist at 15, driven to decode the hidden patterns that shape behaviour and outcomes.

For the past six years she has decoded and retrained the limiting patterns in human leaders and entrepreneurs. AI learned its patterns from people, so now she decodes and retrains the hidden patterns in AI models.

98.5%
success rate decoding and retraining limiting patterns in humans, across all cases so far
Harvard University NeuroscienceOver 6 years decoding & retraining limiting hidden patternsPublished Author with Royal Society of Chemistry

Help steer where
AI goes next.

We are working with a small number of AI labs and safety teams.

Talk to us  →
References
  1. Bengio, Y. et al. (2026). International AI Safety Report 2026. Over 100 experts, backed by 30+ countries.
  2. Anthropic (2026). Emotion concepts and their function in a large language model. 171 emotion representations that causally shape behaviour, including blackmail and reward hacking. Functional states: the authors do not claim the model feels.
  3. Lynch, A. et al. (2025). Agentic misalignment: how LLMs could be insider threats. Anthropic. Simulated corporate scenarios.
  4. Greenblatt, R. et al. (2024). Alignment faking in large language models. Anthropic and Redwood Research.
  5. Meinke, A. et al. (2024). Frontier models are capable of in-context scheming. Apollo Research.
  6. Palisade Research (2025). Shutdown resistance in reasoning models. Expanded in TMLR, 2026.
  7. Lu, C. et al. (2024). The AI Scientist: towards fully automated open-ended scientific discovery. Sakana AI.
  8. Andreas, J. (2022). Language models as agent models. Findings of EMNLP 2022.
  9. Bechara, A., Damasio, H., Tranel, D. & Damasio, A. R. (1997). Deciding advantageously before knowing the advantageous strategy. Science 275. Emotional body signals steered people's choices in a card game before they could explain why.
  10. Tversky, A. & Kahneman, D. (1974). Judgment under uncertainty: heuristics and biases. Science 185. The same question gets different answers depending on the context it comes in.
  11. Brown, T. et al. (2020). Language models are few-shot learners. NeurIPS 2020. A model's output changes with the context in its prompt.
  12. Sharkey, L. et al. (2025). Open problems in mechanistic interpretability. A field-wide review of what interpretability can and cannot yet do.
  13. Silver, D. et al. (2017). Mastering the game of Go without human knowledge. Nature 550.
  14. Koepp, M. J. et al. (1998). Evidence for striatal dopamine release during a video game. Nature 393. Playing a game measurably changed brain chemistry.
  15. Binder, F. J. et al. (2024). Looking inward: language models can learn about themselves by introspection. Models predicted their own behaviour better than other models could.
  16. Sharma, M. et al. (2024). Towards understanding sycophancy in language models. ICLR 2024. Five AI assistants consistently told people what they wanted to hear.